
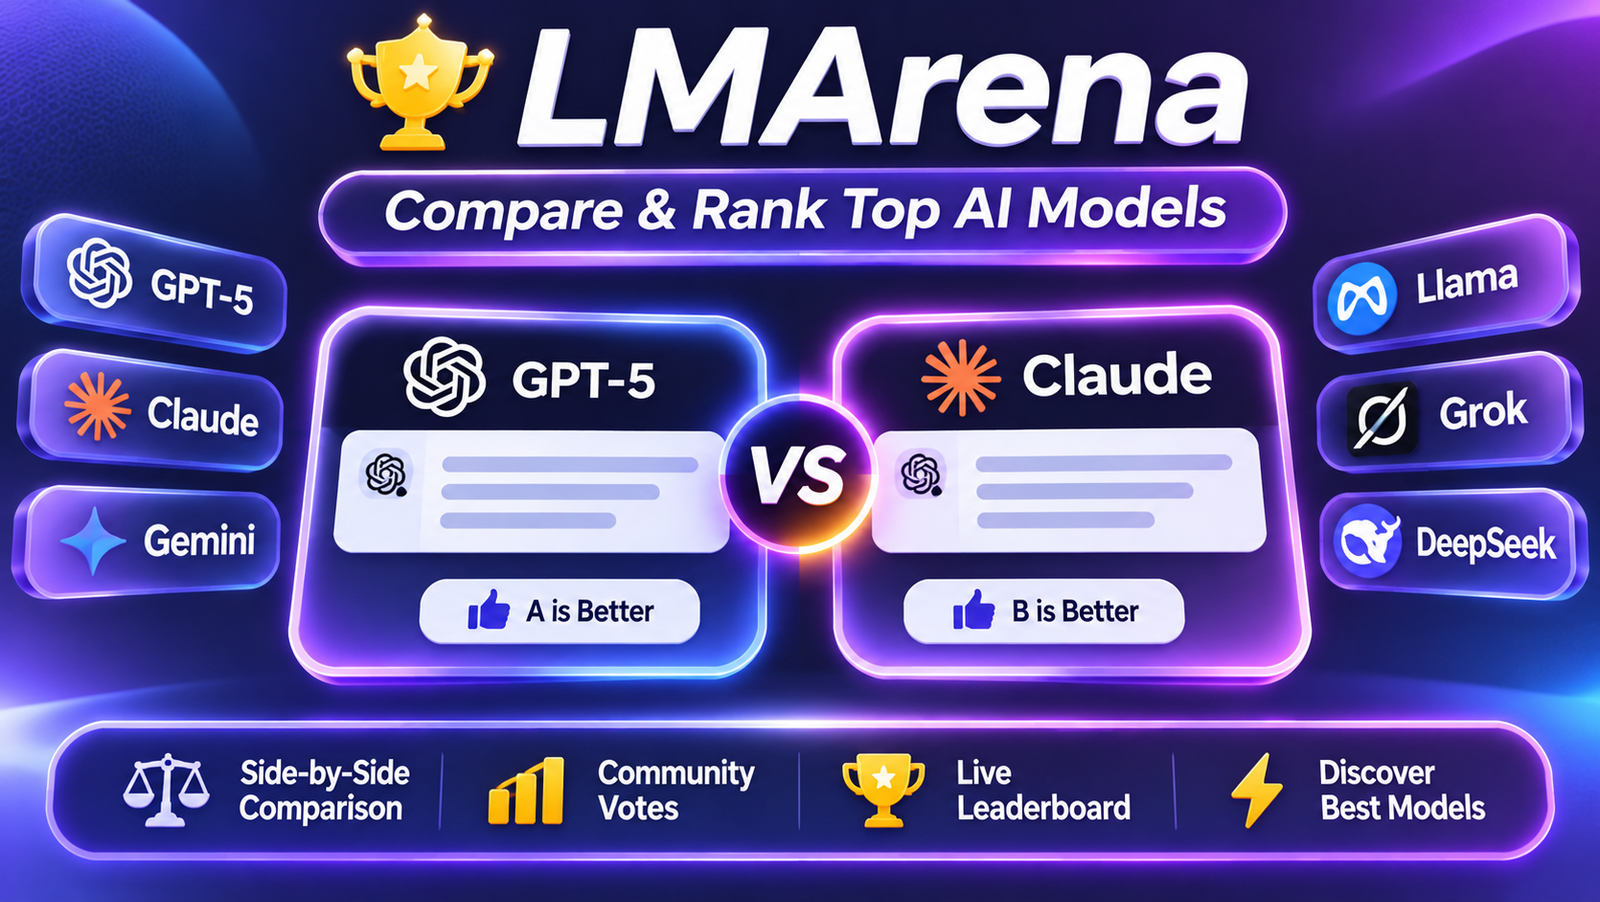
LMArena, which rebranded as simply Arena in January 2026, is the best-known public leaderboard for AI chatbots. Instead of testing models on fixed exam questions, it lets ordinary users put two anonymous AI models side by side, ask them anything, and vote for the better answer. Millions of those blind votes are turned into rankings that AI companies, journalists and developers watch closely.
It started as a university research project and became a company valued at about $1.7 billion in early 2026. This guide explains how it works, how to use it yourself, how to read the leaderboard sensibly, and the criticisms that are worth knowing before you treat any ranking as the final word.
Key facts
- Launched: as Chatbot Arena on 24 April 2023 by researchers linked to UC Berkeley’s LMSYS group.
- Founders listed: Wei-Lin Chiang, Anastasios Angelopoulos and Ion Stoica.
- Became a company: in April 2025, raising a $100 million seed round at a $600 million valuation the following month.
- Series A: $150 million at a post-money valuation of about $1.7 billion, announced in January 2026.
- Rebrand: from LMArena to Arena on 28 January 2026.
Sources: Wikipedia and Latent Space.
Contents
- What LMArena is
- How a battle works
- How votes become rankings
- How to use it, step by step
- A short timeline
- Writing prompts that reveal real differences
- Text, vision, coding and video arenas
- How to read the leaderboard
- Arena vs traditional benchmarks
- Criticisms and controversies
- Privacy: what happens to your prompts
- Using Arena to choose an AI tool
- FAQ
What LMArena is
Traditional AI benchmarks test models on fixed sets of questions, such as maths problems or reading comprehension. They’re useful, but models can be tuned to those tests, and they don’t always reflect what real people care about: helpful, clear, accurate answers to everyday questions.
Chatbot Arena took a different approach in 2023: let the public judge. Anyone could visit the site, type a prompt, see answers from two hidden models and vote. Because users bring their own questions, the leaderboard reflects a huge variety of real tasks, from coding and writing to trivia and advice.
The project grew into the most cited “vibes-based” ranking in AI. According to a January 2026 interview on Latent Space with co-founder Anastasios Angelopoulos, the platform had handled more than 250 million conversations and had over 5 million users. The domain moved to lmarena.ai in 2024, and the company rebranded as Arena in January 2026.
How a battle works
- You type a prompt.
- Two models, chosen by the platform, answer side by side. Their names are hidden.
- You can keep chatting with both to probe further.
- You vote: Model A is better, Model B is better, it’s a tie, or both are bad.
- Only after voting are the models’ names revealed.
The anonymity is the point. If you knew which company made each answer, your expectations would colour your judgement. Blind voting reduces that brand bias.
How votes become rankings
Each vote is a small head-to-head result. Arena uses statistical rating methods, similar in spirit to chess ratings, to turn millions of these results into a single score per model. Early versions used an Elo-style system. The team later moved to a Bradley–Terry model, which estimates each model’s strength from all its wins and losses at once and produces confidence intervals.
Two practical consequences follow:
- Scores are relative. A model’s number only means something compared with other models on the same leaderboard.
- Uncertainty matters. Models with fewer votes have wider confidence intervals, so small gaps near the top are often statistically meaningless. Two models a few points apart may be effectively tied.
How to use it, step by step
- Go to lmarena.ai. You can try it without signing in, though logging in saves your history.
- Choose a mode. Battle gives you two anonymous models. Side by side lets you pick two named models to compare. Direct lets you chat with one model.
- Write a real prompt you actually care about, such as a task from your work or study.
- Compare carefully. Check accuracy, not just confidence. A fluent answer can still be wrong.
- Vote honestly, then see which models you were comparing.
- Check the leaderboard to see how models rank overall and in specific categories.
Tip: use battles to test models on your own kind of work. A model that ranks first overall might not be the best at Urdu translation, legal summaries or Python debugging. Ten minutes of your own blind testing can be more useful than any headline ranking.
A short timeline
| Date | Milestone |
|---|---|
| April 2023 | Chatbot Arena launches as a research project |
| June 2024 | Image input support added |
| September 2024 | Platform moves to the lmarena.ai domain |
| April 2025 | Becomes an independent company; Llama 4 testing controversy |
| May 2025 | $100 million seed round at a $600 million valuation |
| January 2026 | $150 million Series A at about $1.7 billion; video support; rebrand to Arena |
Writing prompts that reveal real differences
Many battles end in a tie because the prompt was too easy. Every modern model can answer “What is the capital of France?”. To see real differences, ask questions that test reasoning, accuracy and judgement:
- Multi-step reasoning: “A shop sells pens at 3 for $2 and notebooks at $4.50. I have $20 and need at least 2 notebooks. What’s the maximum number of pens I can buy? Show your working.”
- Writing with constraints: “Write a 120-word product description for a reusable water bottle aimed at hikers, without using the words ‘eco’ or ‘sustainable’.”
- Coding: paste a short buggy function and ask the models to find and fix the bug, explaining the cause.
- Language and translation: give a sentence with an idiom and ask for a natural translation into another language you speak, then judge the result yourself.
- Honesty: ask about something obscure or fictional and see which model admits uncertainty instead of inventing an answer.
Prompts in your own field are the most revealing, because you can judge accuracy that a general voter couldn’t.
Text, vision, coding and video arenas
Arena has expanded well beyond text chat. Image input support was added in June 2024, and video arrived in January 2026, according to Wikipedia. The platform now runs separate leaderboards for areas such as:
- Text: general chat, with category breakdowns such as coding, maths, creative writing and longer queries.
- Vision: models that understand images you upload.
- Coding and web development: models build working code or web pages, judged by users.
- Image and video generation: models create visuals from prompts, judged side by side.
- Search and specialist arenas: including expert areas the company has discussed, such as medicine, law and finance.
How to read the leaderboard
| What you see | What it means | How to use it |
|---|---|---|
| Rank | Position by estimated score | Treat close ranks as roughly equal |
| Score | Relative strength from head-to-head votes | Compare within the same leaderboard only |
| Confidence interval | How certain the score is | Overlapping intervals mean no clear winner |
| Votes | How many battles the score is based on | More votes, more reliable |
| Category filters | Rankings for specific task types | Use the category closest to your needs |
| Style control | Adjusts for answer length and formatting | Helps separate substance from presentation |
The style control option exists because voters tend to prefer longer, nicely formatted answers. Adjusting for style gives a clearer picture of which models are genuinely more helpful rather than just more verbose.
Arena vs traditional benchmarks
| Arena (human preference) | Traditional benchmarks | |
|---|---|---|
| Who judges | Members of the public, blind | Automatic scoring against answer keys |
| Questions | Whatever users ask, constantly changing | Fixed test sets |
| Strength | Reflects real-world usefulness and preferences | Precise, repeatable measurement of specific skills |
| Weakness | Voter bias toward length and style; harder to audit | Models can be tuned to the test; may not reflect everyday use |
| Best used for | Overall feel and comparison of popular models | Checking specific abilities such as maths or coding accuracy |
The two approaches complement each other. A model that tops both human-preference rankings and demanding technical benchmarks is likely genuinely strong. One that does well on only one deserves a closer look at why.
Criticisms and controversies
Arena’s influence has attracted scrutiny, and several criticisms are worth knowing:
- The Llama 4 episode. In April 2025, a version of Meta’s Llama 4 Maverick scored very highly, but it turned out to be an experimental variant that differed from the publicly released model. Arena updated its policies afterwards, according to Wikipedia.
- “The Leaderboard Illusion”. A 2025 paper by researchers including Cohere staff argued that large labs could privately test many model variants and publish only the best, gaining an advantage. Arena disputed the paper, saying it contained factual errors and misrepresented its testing and sampling practices.
- Vote manipulation. Research has shown that coordinated, rigged votes can shift rankings, so the platform has to defend against manipulation.
- Who votes. Results reflect the people who use the site and the questions they ask, which skew towards tech-savvy users and popular tasks like coding.
- Commercial pressure. As a company that also sells evaluation services, Arena faces questions about independence. It says models cannot pay to appear on, or be removed from, the public leaderboard.
None of this makes the leaderboard useless. It means it should be one input among several, alongside traditional benchmarks, independent reviews and your own testing.
Privacy: what happens to your prompts
Arena warns users that conversations may be shared with AI model providers and can be released publicly for research. That makes it a poor place for anything sensitive. Don’t paste:
- personal details about yourself or others,
- confidential work documents, code or client information,
- passwords, keys or financial details.
Use made-up or anonymised examples when testing models on realistic tasks.
Using Arena to choose an AI tool
If you’re deciding which AI assistant to pay for, a practical process is:
- Check the leaderboard category closest to your work.
- Shortlist two or three models near the top that are available in apps you can actually use.
- Run five to ten blind battles with your own typical tasks.
- Consider price, privacy terms, speed and features such as file uploads or integrations.
- Try the shortlisted tool for a week before committing to an annual plan.
Remember that many AI products bundle several models. Agent tools such as Genspark route tasks to different models behind the scenes, so the leaderboard rank of any single model doesn’t tell the whole story about a product.
Bottom line: Arena is the closest thing the AI world has to a public taste test. It’s free, fun and genuinely informative, especially when you run battles with your own questions. Treat the leaderboard as a guide rather than a verdict, look at confidence intervals and categories instead of a single rank, and keep anything private out of your prompts.
As AI models update every few weeks, rankings shift constantly. If you’re choosing a tool for the long term, revisit the leaderboard and your own blind tests every few months rather than relying on a snapshot.
FAQ
Is LMArena free to use?
Yes. Anyone can run battles and view leaderboards for free.
Is LMArena the same as Chatbot Arena?
Yes. Chatbot Arena launched in 2023, became LMArena, and rebranded as Arena in January 2026.
Who runs Arena?
It began as a UC Berkeley-linked research project and became an independent company in 2025. Wikipedia lists Wei-Lin Chiang, Anastasios Angelopoulos and Ion Stoica as founders.
Is the Arena leaderboard reliable?
It is a useful signal of what real users prefer, especially with lots of votes, but close scores are often ties, and it has known biases. Use it alongside other evidence.
Can AI companies pay to rank higher?
Arena says models cannot pay to get on or off the public leaderboard, though the company does sell separate evaluation services.
Should I enter personal information in Arena?
No. Conversations may be shared with model providers and published for research.
Why did a model’s rank change overnight?
New votes arrive constantly, new models are added, and scores are recalculated. Small movements near the top are normal and often within the margin of error.
Leave a comment